
Multicloud AI & ERP / Cloud AI: Machine Learning & Generative AI
Why it matters
Keyword search misses synonyms and intent. Embedding-based search finds documents that mean the same thing even when the words differ, which is why it sits behind almost every AI assistant and modern search experience.
How it works
From text to nearest neighbors
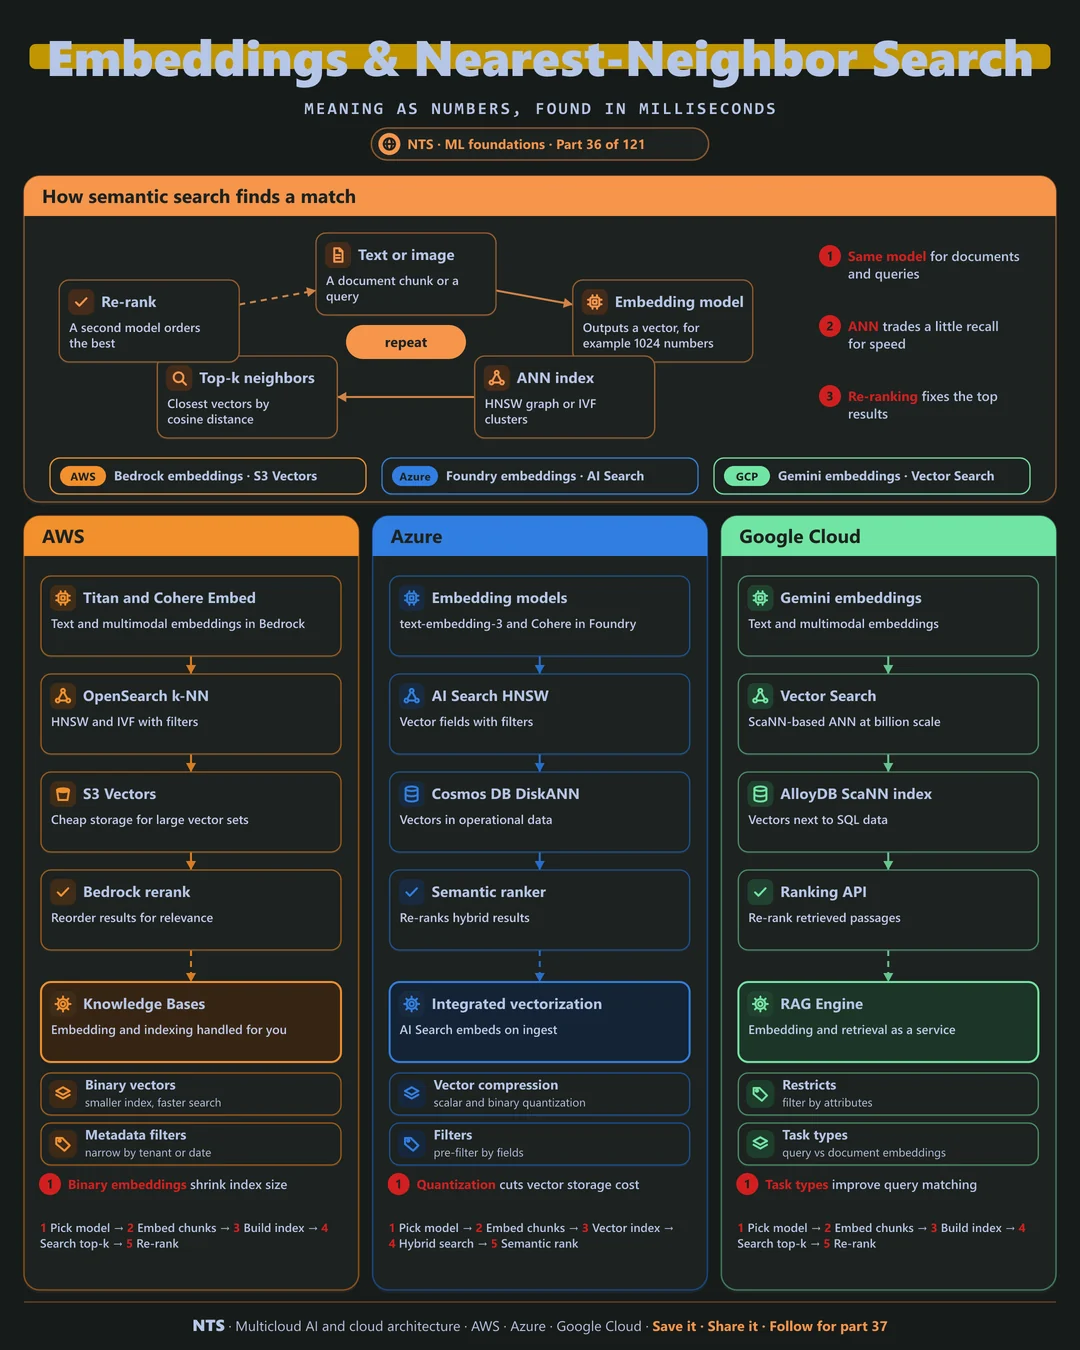
An embedding model turns a text chunk or image into a vector of numbers. Similar meanings land close together. An approximate nearest neighbor (ANN) index such as HNSW finds the closest vectors without comparing every one, trading a little recall for large speed gains.
Re-ranking improves the top results
The fastest retrieval is not always the most precise. A re-ranker model reorders the top candidates for relevance, often lifting answer quality more than changing the main model.
AWS, Azure and Google Cloud compared
| AWS | Azure | Google Cloud | |
|---|---|---|---|
| Embedding models | Titan, Cohere Embed (Bedrock) | OpenAI embeddings, Cohere (Foundry) | Gemini embeddings |
| ANN search | OpenSearch k-NN | Azure AI Search HNSW | Vector Search (ScaNN) |
| Low-cost vector storage | S3 Vectors | Cosmos DB DiskANN | AlloyDB ScaNN |
| Re-ranking | Bedrock rerank models | Semantic ranker | Ranking API |
| Compression | Binary embeddings | Scalar and binary quantization | Output dimensionality control |
What makes each cloud different
AWS
Bedrock offers Titan and Cohere embedding models and rerank models, OpenSearch provides HNSW and IVF indexes with filters, and S3 Vectors stores very large vector sets at low cost.
Azure
Azure AI Search supports vector fields with HNSW, scalar and binary quantization to cut storage, and a semantic ranker that re-orders hybrid results. Cosmos DB adds DiskANN vector search inside operational data.
Google Cloud
Gemini embeddings support task types that distinguish queries from documents, improving matching. Vector Search uses ScaNN at very large scale, and the Ranking API re-ranks retrieved passages.
Design decisions that matter
- 01One embedding model per index
Never mix models in the same index.
- 02Version the index
Re-embed into a new index, then switch.
- 03Add a re-ranker
Cheap way to improve top results.
- 04Compress where possible
Quantization cuts cost with little quality loss.
Common mistakes we see
- Changing models in place. Old and new vectors are not comparable.
- No evaluation set. You cannot tell whether retrieval improved.
- Chunks that are too large. Relevant sentences drown in noise.
A practical 30-day plan
- Week 1
Build an evaluation set of real queries and correct documents.
- Week 2
Compare two embedding models and chunk sizes.
- Week 3
Add a re-ranker and measure the gain.
- Week 4
Apply compression and set up index versioning.
How NTS helps
NTS builds semantic search on AWS, Azure and Google Cloud, choosing embedding models, tuning chunking and ranking and measuring retrieval quality with real evaluation sets.
What you get
- Embedding model selection and testing
- Approximate nearest-neighbor indexes tuned for recall and speed
- Pipelines to embed and refresh content
- Retrieval quality metrics
Typical outcomes
- More relevant search and recommendations
- Fast queries at large scale
- Better grounding for AI assistants
How we work with you
- 1Assess
A focused review of your embeddings and semantic search across AWS, Azure and Google Cloud. We look for the gaps we find most often: changing models in place, no evaluation set and chunks that are too large.
- 2Design
A target architecture and roadmap built on the decisions that matter most: one embedding model per index, version the index, add a re-ranker and compress where possible.
- 3Build
Hands-on delivery alongside your team. We build an evaluation set of real queries and correct documents, compare two embedding models and chunk sizes, add a re-ranker and measure the gain, and finally apply compression and set up index versioning.
- 4Run and improve
We refresh embeddings, re-tune indexes and test new embedding models over time.
Why teams choose NTS for embeddings and semantic search
- Recall and speed balanced
We tune indexes to find the right results quickly.
- Measured relevance
We prove search quality with test sets.
- Fits your stack
Embeddings integrate with your existing databases and search.
Book a free 30-minute review
Talk to an NTS architect about your embeddings and semantic search on AWS, Azure and Google Cloud.