
Multicloud AI & ERP / Cloud AI: Machine Learning & Generative AI
Why it matters
RAG is the most common enterprise AI pattern: assistants over policies, contracts, manuals and tickets. When answers are wrong, the cause is usually retrieval, not the model, and switching to a bigger model rarely helps.
How it works
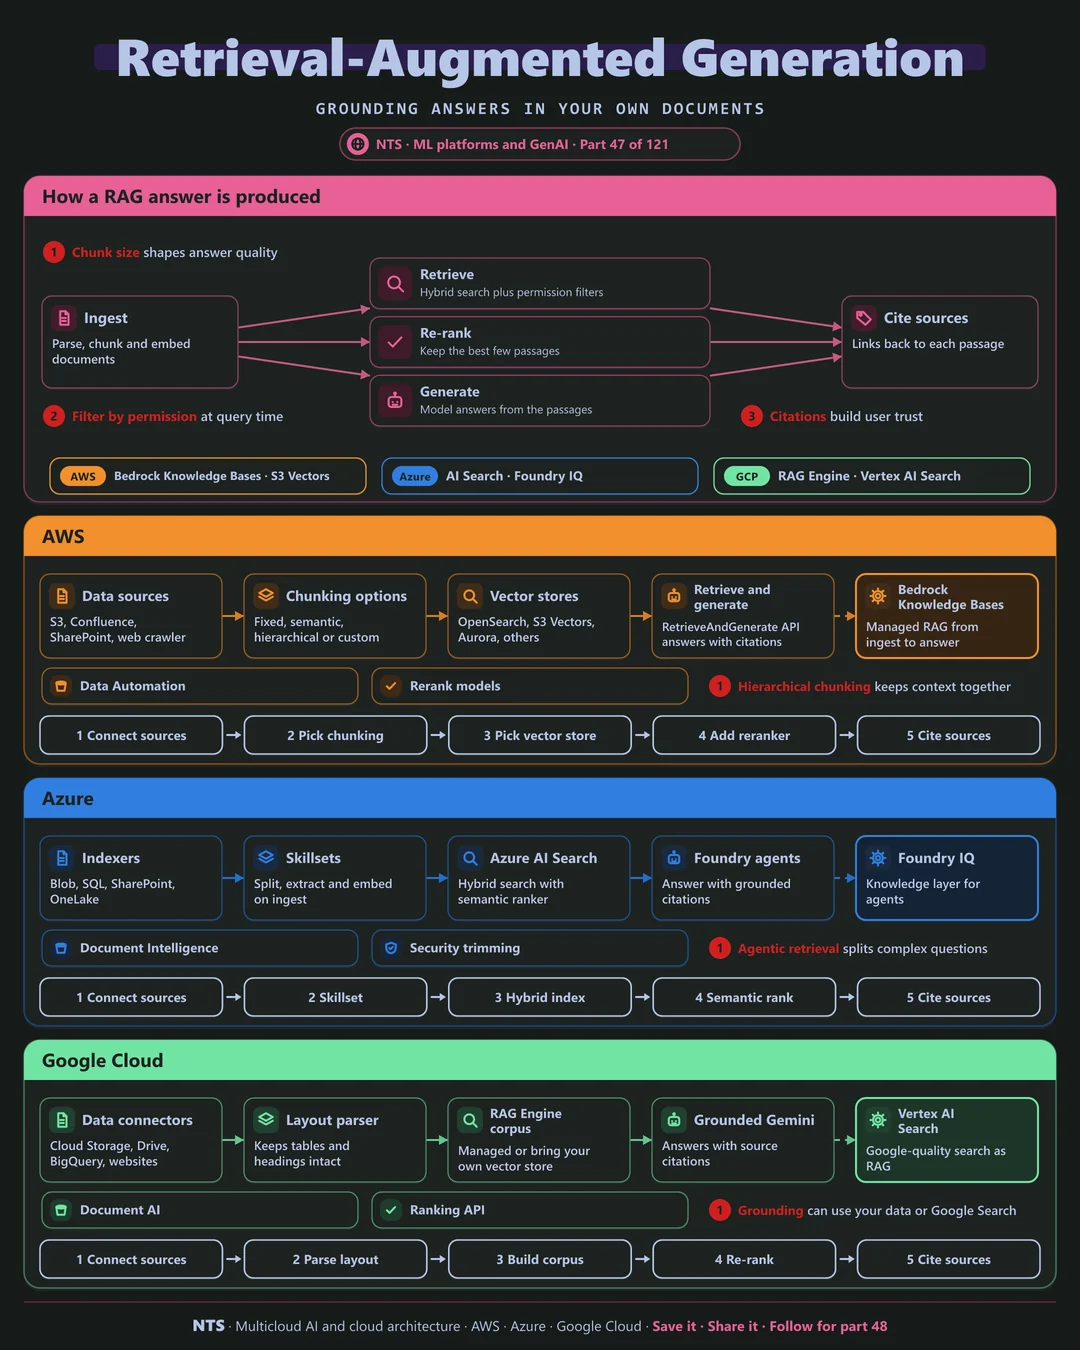
How a RAG answer is produced
Documents are parsed, split into chunks and embedded. At question time, hybrid search finds candidate chunks, filtered by the user's permissions. A re-ranker keeps the best few, and the model generates an answer grounded in them, with citations back to each source.
Where quality comes from
Layout-aware parsing keeps tables and headings intact, chunk size balances context and precision, and re-ranking lifts the right passages to the top. Measure retrieval with an evaluation set before tuning the model.
AWS, Azure and Google Cloud compared
| AWS | Azure | Google Cloud | |
|---|---|---|---|
| Managed RAG | Bedrock Knowledge Bases | Azure AI Search, Foundry IQ | RAG Engine, Vertex AI Search |
| Document parsing | Bedrock Data Automation | Document Intelligence | Document AI layout parser |
| Retrieval | OpenSearch, S3 Vectors, Aurora | Hybrid search, semantic ranker | Managed corpus or your vector store |
| Re-ranking | Rerank models | Semantic ranker | Ranking API |
| Permission filtering | Metadata filters | Security trimming | Access control on data stores |
What makes each cloud different
AWS
Bedrock Knowledge Bases handle ingestion from S3, Confluence, SharePoint and the web, with fixed, semantic or hierarchical chunking, a choice of vector stores and answers with citations.
Azure
Azure AI Search provides hybrid retrieval with a semantic ranker, integrated vectorization and agentic retrieval that splits complex questions. Foundry IQ offers a knowledge layer for agents.
Google Cloud
Google's RAG Engine and Vertex AI Search provide managed retrieval, the layout parser keeps document structure, and Gemini can ground answers on your data or on Google Search.
Design decisions that matter
- 01Evaluate retrieval separately
Know whether the right passages were found.
- 02Permission-aware retrieval
Filter at query time, every time.
- 03Hybrid search plus re-ranking
The strongest default for business content.
- 04Always cite sources
Users can verify, and trust grows.
Common mistakes we see
- Swapping models to fix retrieval. The right passages still are not found.
- Ignoring document layout. Tables and lists become nonsense chunks.
- Stale indexes. Answers cite policies that changed months ago.
A practical 30-day plan
- Week 1
Collect 50 real questions with correct answers and sources.
- Week 2
Build the pipeline with layout-aware parsing.
- Week 3
Tune chunking, hybrid search and re-ranking.
- Week 4
Add permission filters, citations and index refresh.
How NTS helps
NTS builds production RAG on Bedrock, Azure AI Search and Agent Platform: document parsing, retrieval tuning, permission-aware search, citations and evaluation, so assistants answer correctly and safely.
What you get
- A production RAG architecture on your cloud
- Document ingestion with smart chunking
- Hybrid search with re-ranking and citations
- Evaluation of answer quality and faithfulness
Typical outcomes
- Accurate answers from company knowledge
- Fewer hallucinations
- Faster access to information for employees and customers
How we work with you
- 1Assess
A focused review of your RAG and grounded AI across AWS, Azure and Google Cloud. We look for the gaps we find most often: swapping models to fix retrieval, ignoring document layout and stale indexes.
- 2Design
A target architecture and roadmap built on the decisions that matter most: evaluate retrieval separately, permission-aware retrieval, hybrid search plus re-ranking and always cite sources.
- 3Build
Hands-on delivery alongside your team. We collect 50 real questions with correct answers and sources, build the pipeline with layout-aware parsing, tune chunking, hybrid search and re-ranking, and finally add permission filters, citations and index refresh.
- 4Run and improve
We monitor answer quality, refresh content and tune retrieval as your knowledge base grows.
Why teams choose NTS for RAG and grounded AI
- Answers you can trust
Every answer is grounded in your documents with citations.
- Quality measured, not guessed
We test retrieval and answers against real questions.
- Permission-aware
Users only see answers from documents they are allowed to read.
Book a free 30-minute review
Talk to an NTS architect about your RAG and grounded AI on AWS, Azure and Google Cloud.