
Multicloud AI & ERP / Agentic AI & Cloud AI Infrastructure
Why it matters
AI costs scale with usage in ways traditional budgets did not anticipate. A popular feature can multiply token spend in weeks. Without attribution and optimization, AI programs lose funding just as they start working.
How it works
Cutting cost per answer
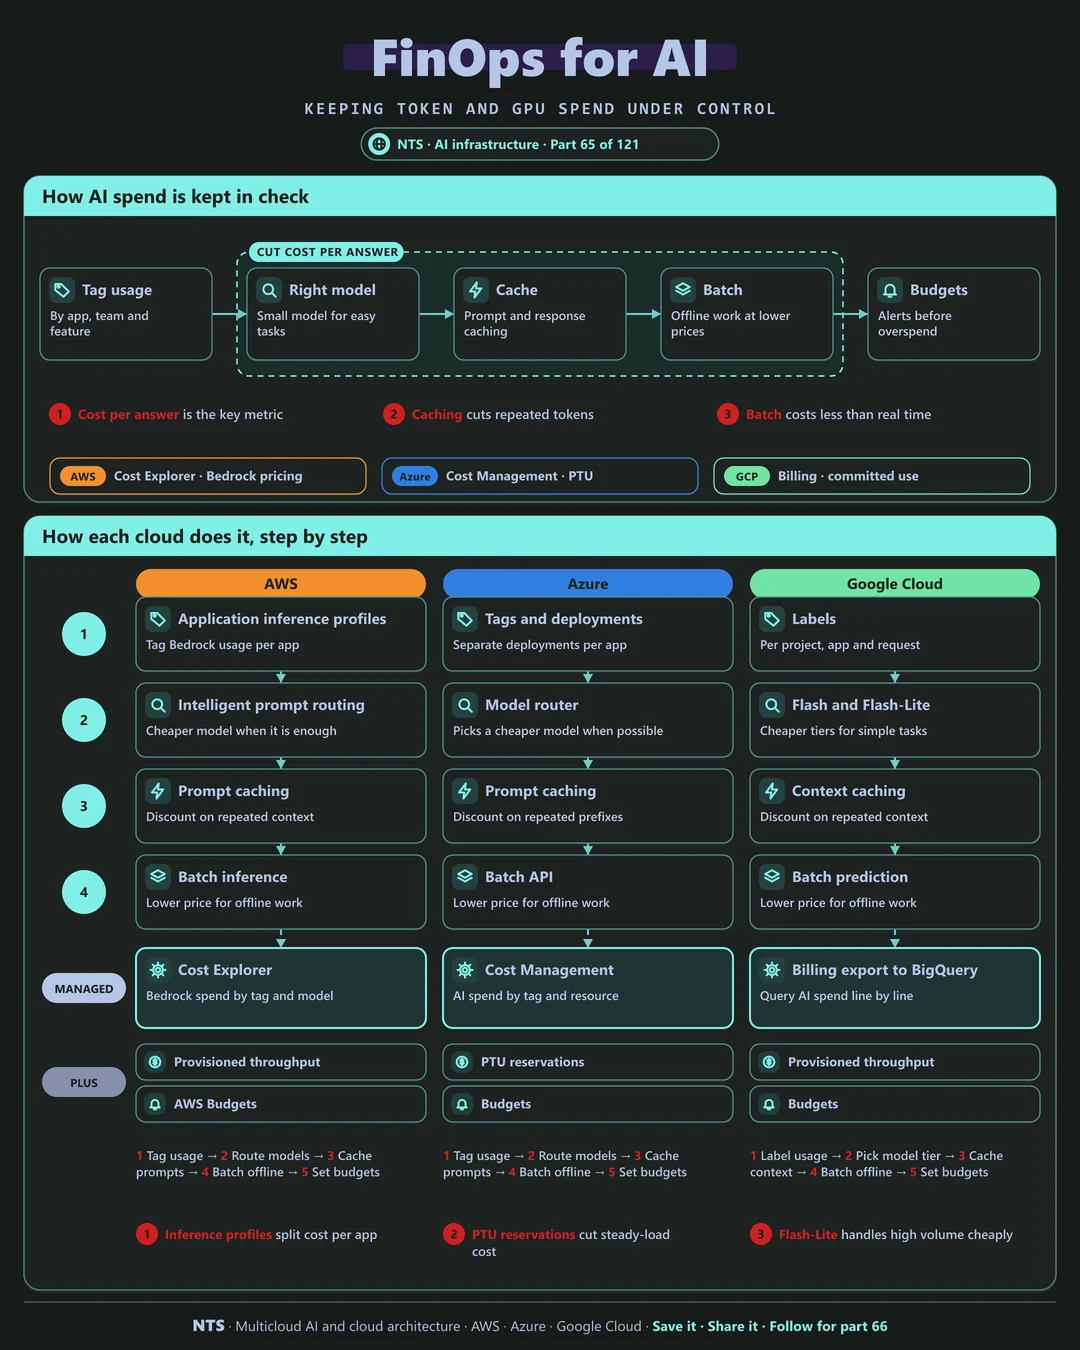
Tag usage by app, team and feature. Route easy requests to smaller models. Cache prompts and repeated responses. Move offline work to batch pricing, and set budgets with alerts before overspend.
AWS, Azure and Google Cloud compared
| AWS | Azure | Google Cloud | |
|---|---|---|---|
| Usage attribution | Application inference profiles | Separate deployments and tags | Labels per project and request |
| Cheaper model routing | Intelligent prompt routing | Model router | Flash and Flash-Lite tiers |
| Caching | Prompt caching | Prompt caching | Context caching |
| Batch discounts | Batch inference | Batch API | Batch prediction |
| Reserved capacity | Provisioned throughput | PTU reservations | Provisioned throughput |
What makes each cloud different
AWS
AWS application inference profiles tag Bedrock usage per application for cost allocation, intelligent prompt routing picks cheaper models when good enough and batch inference halves prices for offline work on supported models.
Azure
Azure separates costs by deployment and tag, the model router chooses cost-effective models per request, and PTU reservations cut the cost of steady high-volume workloads.
Google Cloud
Google's billing export to BigQuery makes AI spend queryable line by line, Flash-Lite serves high-volume simple tasks cheaply and context caching discounts repeated context.
Design decisions that matter
- 01Cost per answer as a KPI
Tracked per feature.
- 02Route by difficulty
Large models only where needed.
- 03Cache aggressively
System prompts and repeated questions.
- 04Budgets with alerts
Catch runaway usage in a day.
Common mistakes we see
- One untagged AI account. Nobody knows which feature costs what.
- Premium models for everything. Simple tasks at frontier prices.
- Ignoring output tokens. Verbose answers quietly double costs.
A practical 30-day plan
- Week 1
Tag AI usage by app and feature.
- Week 2
Enable caching and output limits.
- Week 3
Route simple tasks to smaller models.
- Week 4
Move offline work to batch and set budgets.
How NTS helps
NTS brings FinOps to AI on AWS, Azure and Google Cloud: usage attribution, model routing, caching, batch strategies and capacity planning, keeping AI programs affordable as they scale.
What you get
- AI cost visibility by team, feature and model
- Token and GPU optimization plan
- Budgets and alerts for AI spending
- Model routing to cheaper options where quality allows
Typical outcomes
- Lower AI bills
- Clear cost per AI feature
- No surprise invoices from runaway usage
How we work with you
- 1Assess
A focused review of your AI cost management across AWS, Azure and Google Cloud. We look for the gaps we find most often: one untagged AI account, premium models for everything and ignoring output tokens.
- 2Design
A target architecture and roadmap built on the decisions that matter most: cost per answer as a KPI, route by difficulty, cache aggressively and budgets with alerts.
- 3Build
Hands-on delivery alongside your team. We tag AI usage by app and feature, enable caching and output limits, route simple tasks to smaller models, and finally move offline work to batch and set budgets.
- 4Run and improve
We review AI spending monthly and adjust routing, caching and commitments.
Why teams choose NTS for AI cost management
- AI-specific FinOps
We understand tokens, GPUs and commitments in depth.
- Savings without quality loss
We prove quality holds before switching to cheaper models.
- Unit economics
You see the cost of each AI feature and request.
Book a free 30-minute review
Talk to an NTS architect about your AI cost management on AWS, Azure and Google Cloud.