
Multicloud AI & ERP / Cloud Migration, Integration & AI Operations
Why it matters
On-premises HPC clusters are either too small at peak or idle most of the time. Cloud batch and HPC services scale to the job, then to zero, and Spot capacity cuts the cost of retryable work dramatically.
How it works
How a batch or HPC job runs
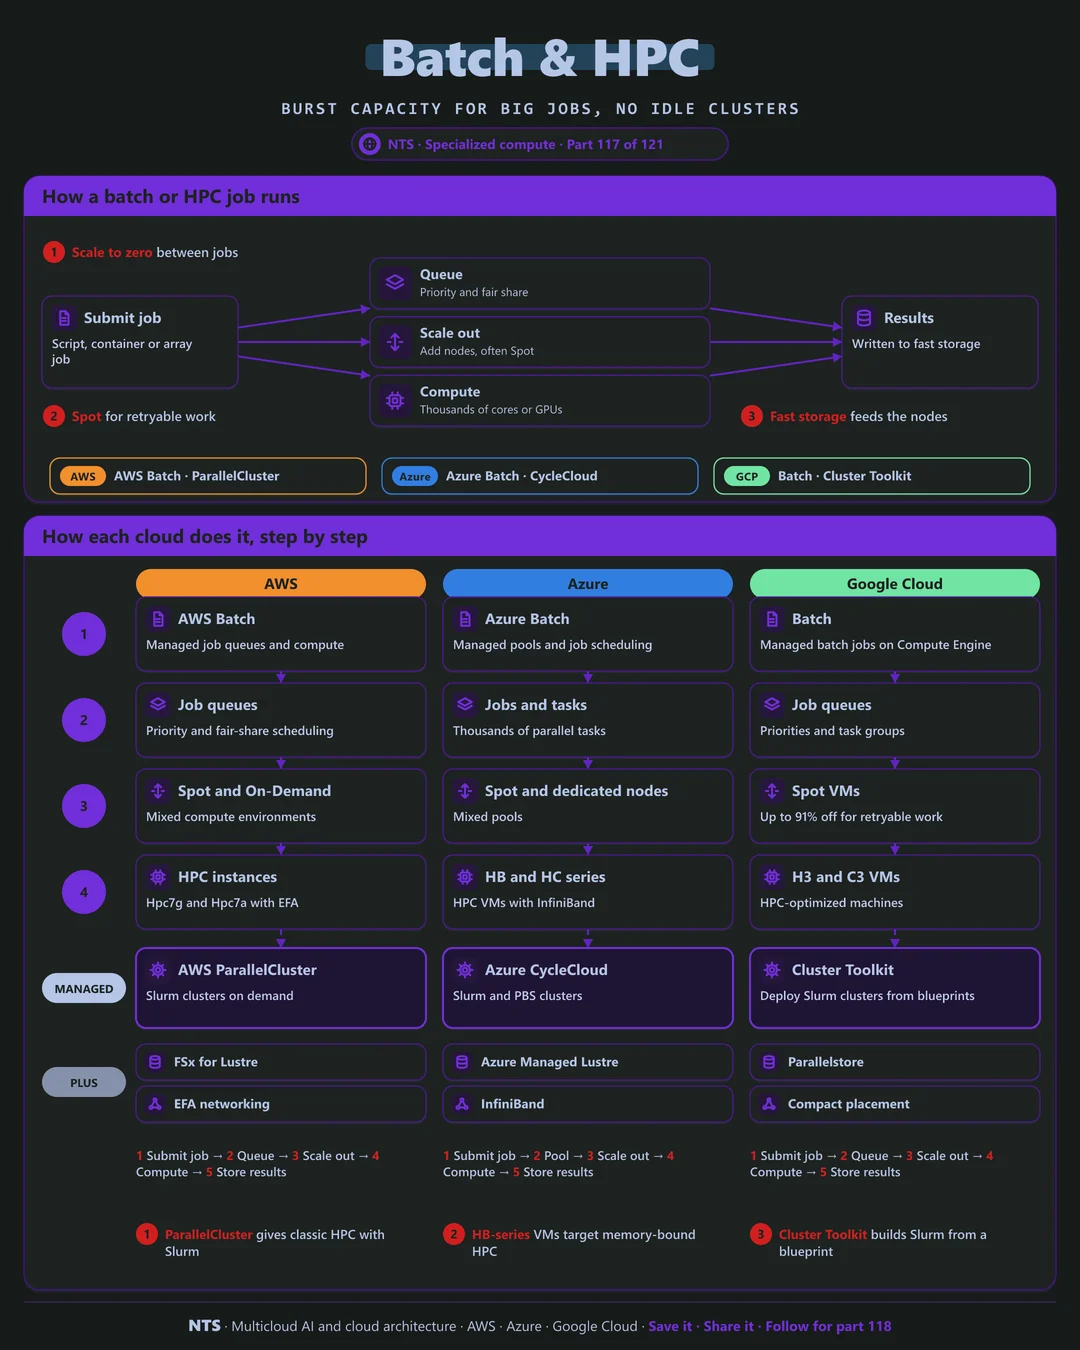
Users submit jobs to a queue with priorities and fair share. The scheduler scales out compute, often on Spot, runs the work across thousands of cores or GPUs and writes results to fast storage, then scales back to zero.
AWS, Azure and Google Cloud compared
| AWS | Azure | Google Cloud | |
|---|---|---|---|
| Managed batch | AWS Batch | Azure Batch | Batch |
| HPC clusters (Slurm) | AWS ParallelCluster | Azure CycleCloud | Cluster Toolkit |
| HPC instances | Hpc7g, Hpc7a with EFA | HB and HC series with InfiniBand | H3 and C3 VMs |
| Fast shared storage | FSx for Lustre | Azure Managed Lustre | Parallelstore, Managed Lustre |
| Spot pricing | Spot Instances | Spot VMs | Spot VMs (up to 91% off) |
What makes each cloud different
AWS
AWS Batch manages job queues and compute environments that mix Spot and On-Demand, while AWS ParallelCluster builds classic Slurm clusters with EFA networking and FSx for Lustre.
Azure
Azure Batch runs large parallel workloads, Azure CycleCloud builds Slurm and PBS clusters and HB-series VMs with InfiniBand target memory-bound HPC applications.
Google Cloud
Google's Batch runs managed jobs on Compute Engine, and the Cluster Toolkit deploys Slurm clusters from blueprints with compact placement for low-latency MPI.
Design decisions that matter
- 01Scale to zero between jobs
No idle clusters.
- 02Spot for retryable work
With checkpoints.
- 03Fast storage sized for throughput
Keep cores busy.
- 04Keep familiar schedulers
Slurm in the cloud eases adoption.
Common mistakes we see
- Always-on cloud clusters. On-premises economics in the cloud.
- Ignoring data movement. Jobs wait on transfers.
- Spot without checkpoints. Lost work on interruption.
A practical 30-day plan
- Week 1
Profile current HPC workloads and peaks.
- Week 2
Deploy a cloud Slurm or batch environment.
- Week 3
Run real jobs with Spot and checkpoints.
- Week 4
Compare time to result and cost.
How NTS helps
NTS builds cloud HPC and batch environments on AWS, Azure and Google Cloud for engineering, life sciences and media workloads, covering schedulers, storage, networking and Spot strategies.
What you get
- Cloud HPC clusters with Slurm or managed batch
- Fast shared storage sized for throughput
- Spot strategies with checkpointing
- Cost and time-to-result comparisons
Typical outcomes
- Shorter queue times for researchers and engineers
- Lower compute costs with Spot
- Faster time to results
How we work with you
- 1Assess
A focused review of your batch and HPC across AWS, Azure and Google Cloud. We look for the gaps we find most often: always-on cloud clusters, ignoring data movement and Spot without checkpoints.
- 2Design
A target architecture and roadmap built on the decisions that matter most: scale to zero between jobs, Spot for retryable work, fast storage sized for throughput and keep familiar schedulers.
- 3Build
Hands-on delivery alongside your team. We profile current HPC workloads and peaks, deploy a cloud Slurm or batch environment, run real jobs with Spot and checkpoints, and finally compare time to result and cost.
- 4Run and improve
We tune clusters, storage and costs as workloads change.
Why teams choose NTS for batch and HPC
- Burst without idle clusters
Capacity scales up for jobs and down to zero after.
- HPC experience
We understand schedulers, MPI and parallel storage.
- Spot savings, safely
Checkpoints protect work when capacity is reclaimed.
Book a free 30-minute review
Talk to an NTS architect about your batch and HPC on AWS, Azure and Google Cloud.